Kits AI
Kits Data Sourcing
Quality in, quality out: how Kits data powers AI for professional use
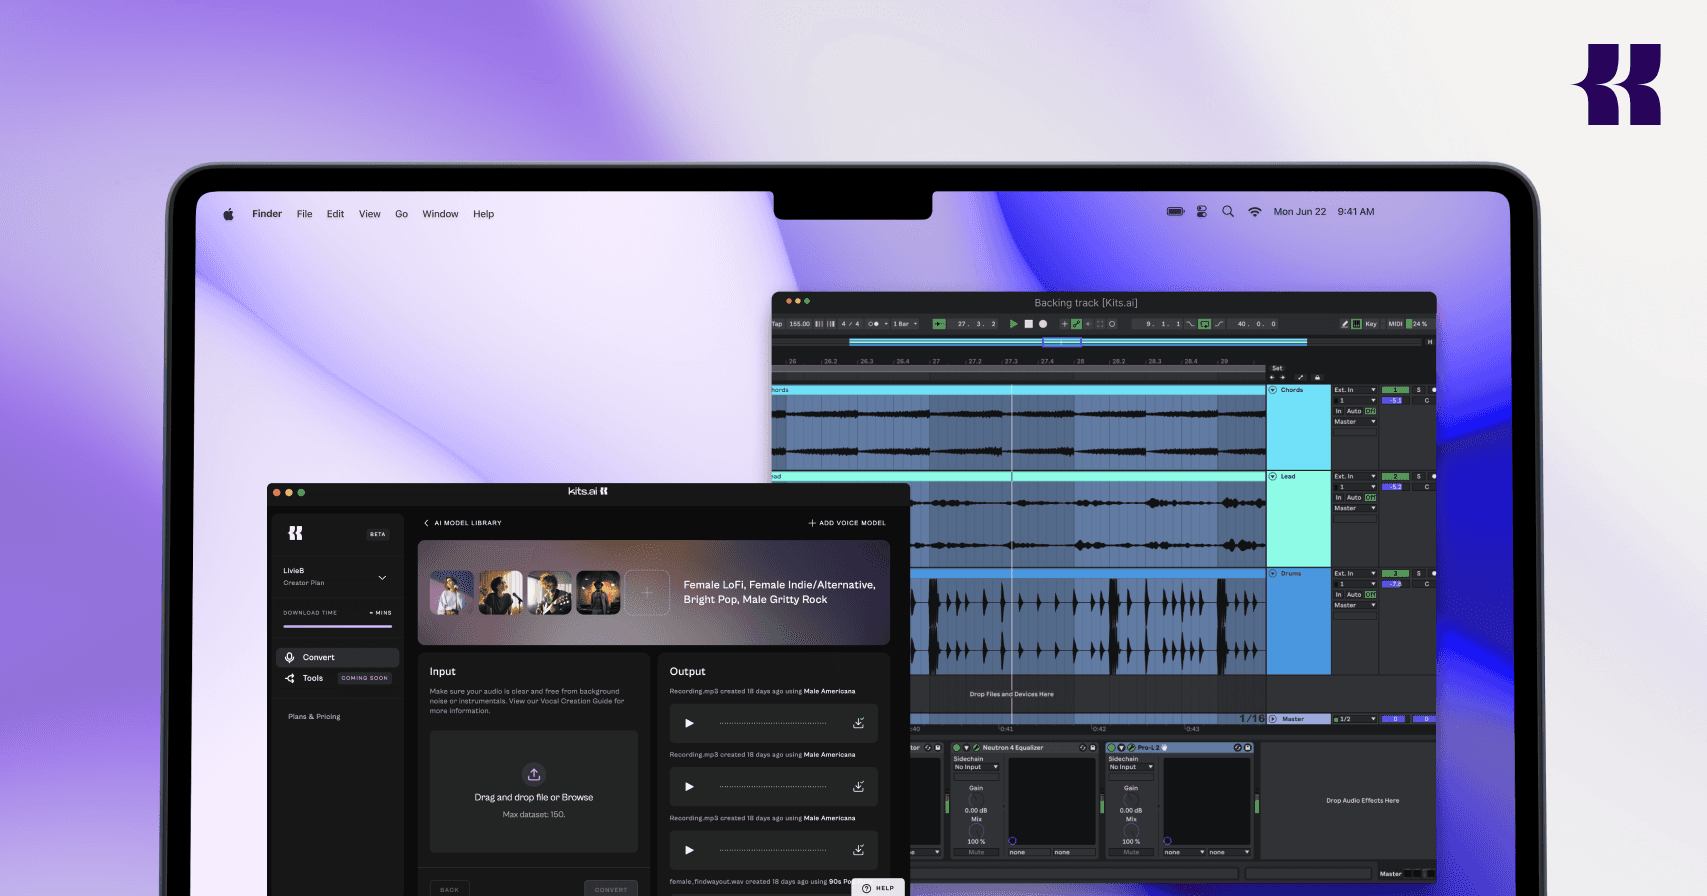
Quality in, quality out: How Kits data powers AI for professional use
An AI model’s performance hinges as much on the quality of its training data as on its architecture. At Kits.AI, we’re uncompromisingly committed to sourcing the highest quality data to build AI tools that are release-ready for music industry pros around the world.
We also recognize that AI music tools don’t exist in a vacuum. We operate in an industry that thrives on human creativity, and so all of our data is licensed directly from artists who benefit financially from the use of their recordings.
This article demonstrates a few of the many ways that meticulous data practices provide the bedrock for high-quality, ethical AI.
Release-ready royalty free voices
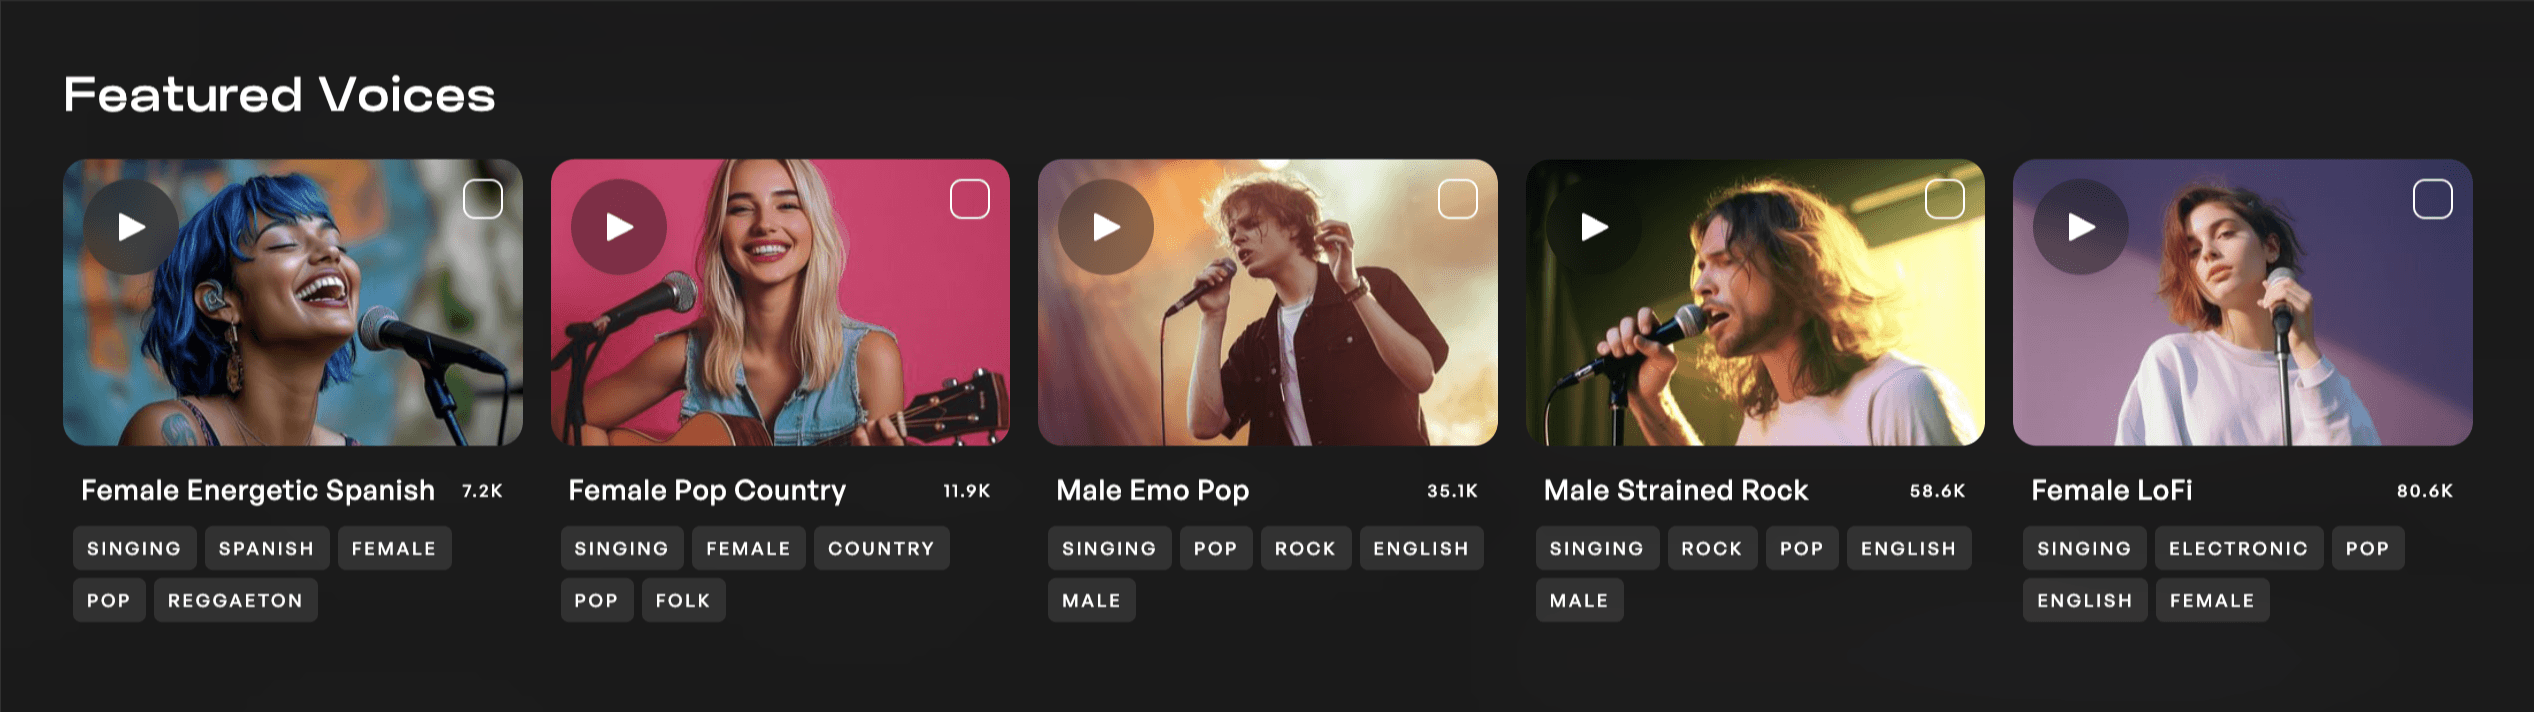
The Kits Royalty Free Library provides studio-quality voice clones that millions of music producers around the world can use in their music with commercial, royalty-free licenses. From airy falsettos to fried rock tones, this vocal palette provides producers with limitless creative choices.
Listen to a few examples:
Male Bright Pop
Female Warm Pop
Female Smooth Rock
Each voice in the library is sourced directly from an artist who is compensated for the use of their training data. To respect the rapidly changing ways that AI fits into their careers, these artists have the option to opt out at any time. Our training data, data sourcing and data management practices are certified as Fairly Trained.
Open Source vs. Kits Data
Open-sourced data powers many meaningful projects in the text-to-speech and voice conversion space, but it comes with limitations. Kits data is curated and processed to adhere to the following quality pillars:
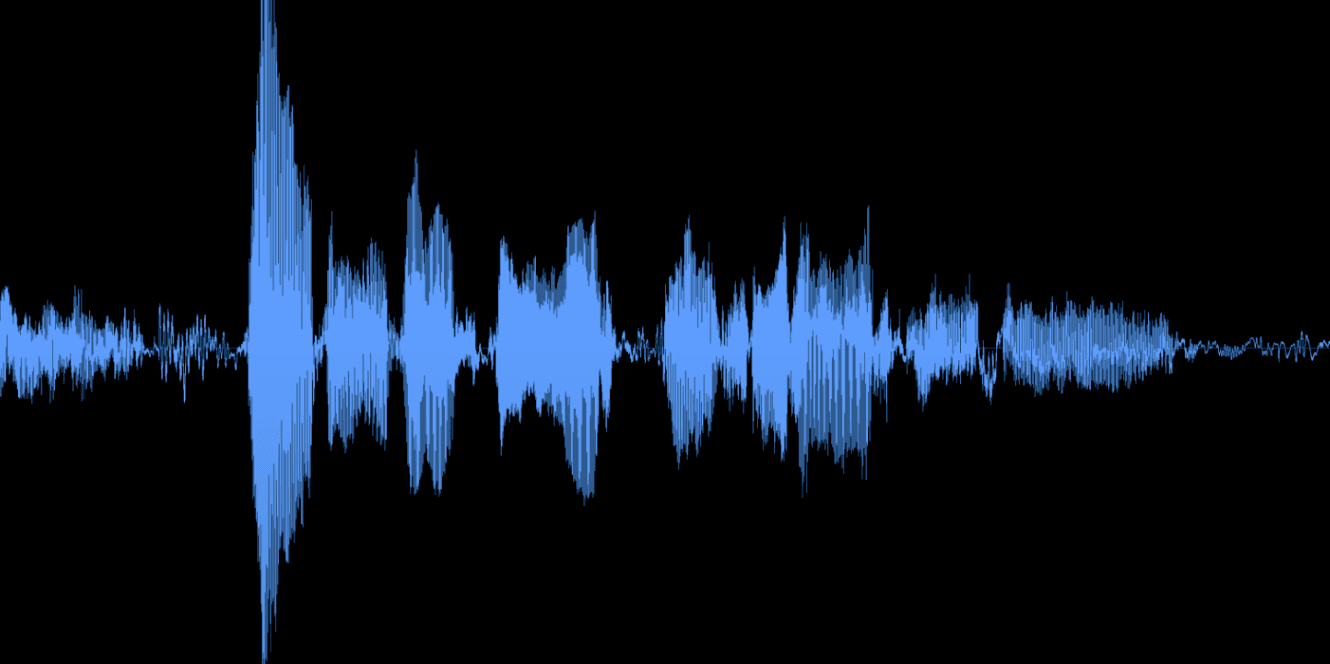
Open-source data with loud peaks & NOISE.
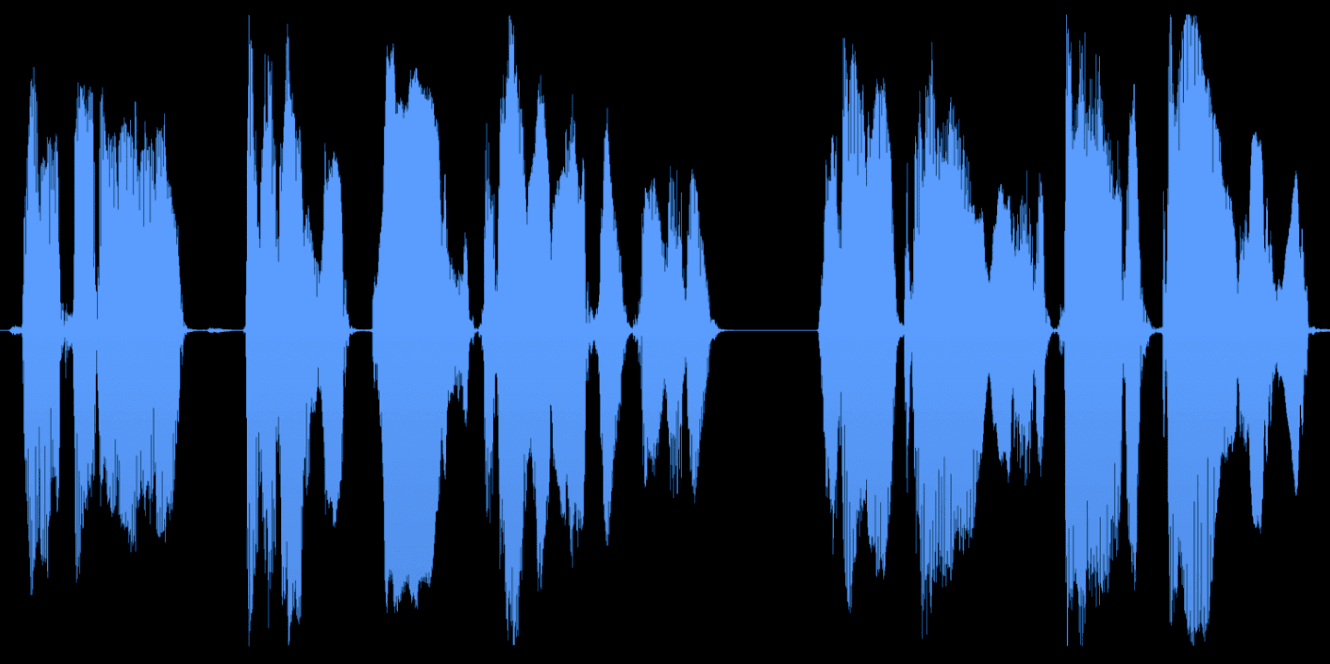
Kits data with Consistent VOLUME AND NO NOISE.
Consistency:
All Kits data is manually processed by expert audio engineers to maintain consistency across frequency response, peak and average loudness levels, phase rotation, sampling rate, and more. With open sourced datasets, inconsistency in these areas can add undesirable variation that limits model quality.
Signal-to-noise ratio:
From microphone quality to acoustic treatment, Kits defines detailed guidelines on to prevent unwanted noise in training data. A consistently low noise floor in training data results in more effective voice cloning and cleaner conversions.
Cleanliness:
Stem splitting technology has become astonishingly good. But vocal data extracted from songs is still likely to have reverb, harmonies, instrumental bleed, or other stem splitting artifacts.
Kits data comes right off the microphone for a guaranteed clean, monophonic recording.
Post-Processing
Vocal engineering itself is an art. Our in-house engineers meticulously process each dataset to apply the perfect amount of stylistic polish. Perfectly compressed consonants and clear and resonant vowels carry through to make Kits voices versatile and release-ready.
Pre-Trained Weights
When you clone a voice with Kits.AI, you’re capturing all the nuance, expressiveness, and natural sound of that voice.
But your voice clone doesn't start from zero. Instead, it starts with a starter model (or “pre-trained weight”) that understands the generalities of what voices sound like. A good starting point dramatically cuts down on training time and provides a quality baseline for your voice clone.
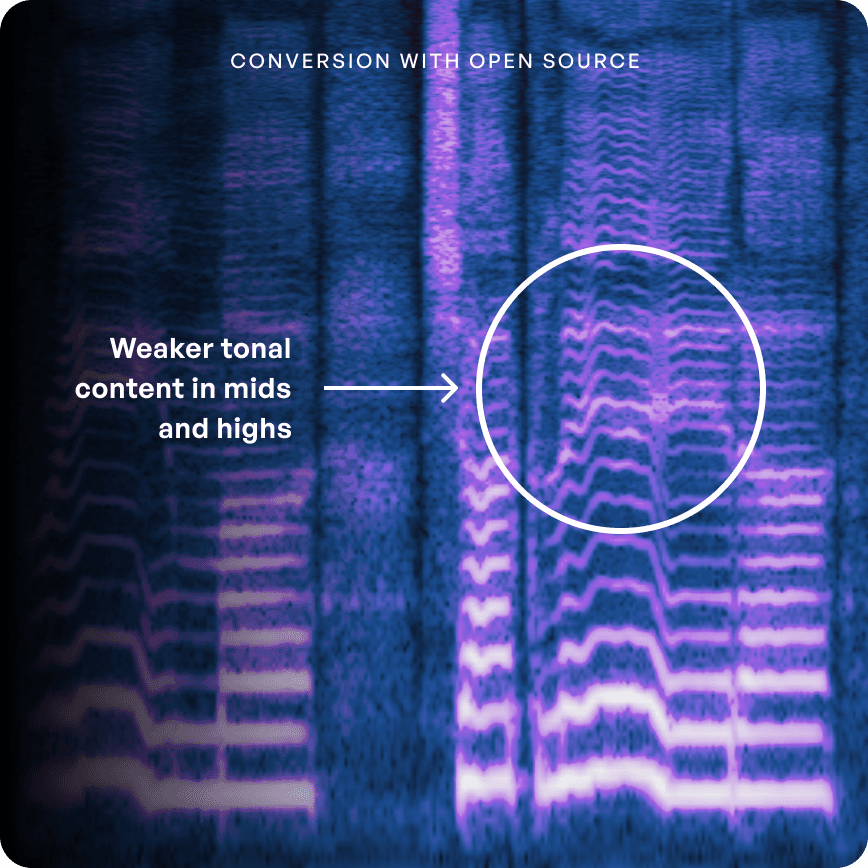
Unlike open-source pre-trained weights, which lack exposure to singing data, Kits models come pre-trained on hand-edited singing data, covering a broad spectrum of vocal styles and techniques. Listen to a few comparisons between voice clones that use open sourced pre-trained weights and voice clones trained with Kits.
Open Source Pre-Trained (VCTK)
Kits Pre-Trained
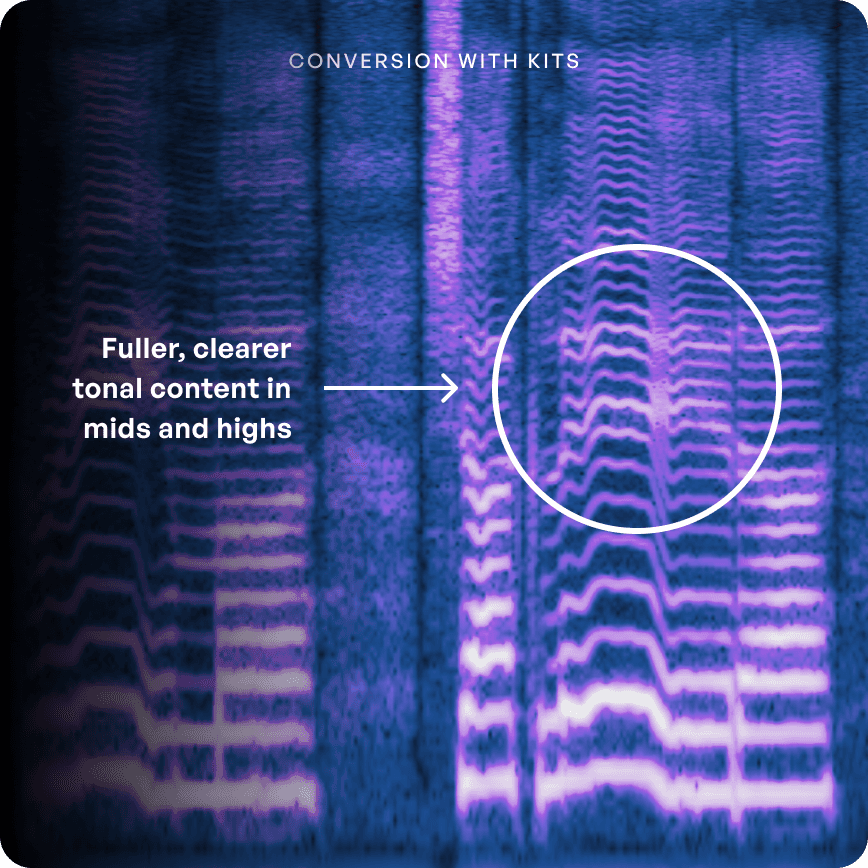
Where Open Source weights are largely trained on speech data, Kits pre-trained weights are optimized for singing. The result: fuller, clearer notes across (and even beyond) the range of a singer.
Open Source Pre-Trained (VCTK)
Kits Pre-Trained
With Kits, the nuances of a vocal performance are reproduced much more realistically than with Open Source pre-trained weights.
A Commitment to Ethical AI
We believe that empowering the next generation of music producers starts with empowering the artists whose voices make this possible. That’s why Kits.AI research relies only on licensed training data sourced directly from artists.
Our royalty free voice and instrument models are certified Fairly Trained, which means every part of our data pipeline from sourcing to management has been vetted for fairness. This isn’t just a badge; it’s a commitment to contributing to the creative industry we operate within.
At Kits.AI, we’re building more than AI technology; we’re creating a foundation for ethical, high-quality music production tools that set a new standard in the industry. As we continue expanding our voice library and refining our models, we remain committed to quality, transparency, and innovation—empowering producers with tools they can trust.
Start creating with Kits
Explore voice conversion, voice creation and audio tools. Review current plans and account terms in the app.
Get started free